One of the most devastating and unpredictable latency intruders is the Java Virtual Machine’s “stop the world” pauses for garbage collection (memory clean-up). This post troubleshoots an unexpected shutdown of RegionServer fundamentally caused by Full GC and makes the whole process clear.
A Troubleshooting Link to heading
You Are Dead Link to heading
A RegionServer stops, and the logs say:
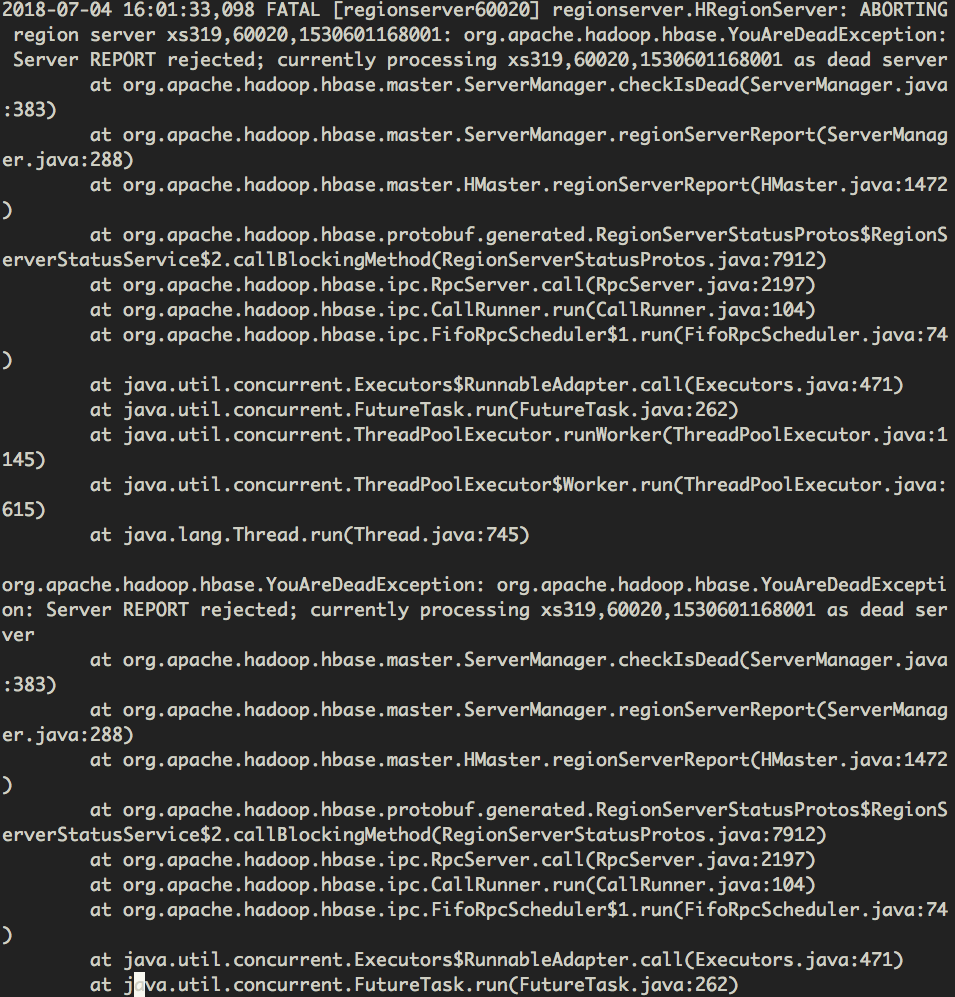
RegionServer throws a YouAreDeadException when checking if it is alive from HMaster. Unfortunately, HMaster marks it as dead, so the RegionServer have to suicide.
Why HMaster deems that a RegionServer still running dies?
Lease Expired Link to heading
Scroll up the logs, and it’s easy to find:
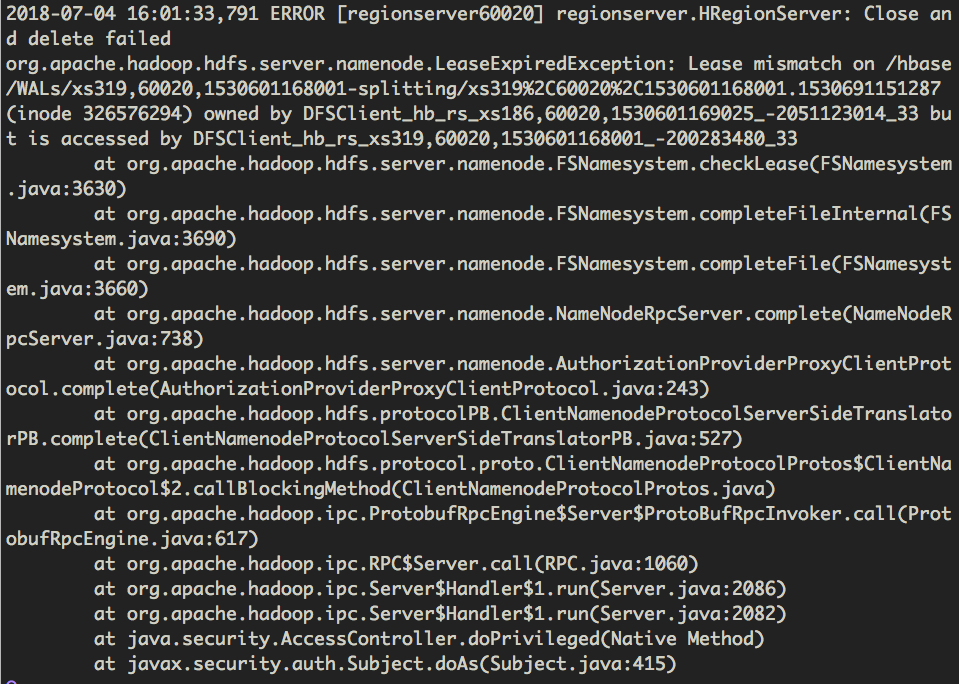
The lease with HDFS NameNode is expired, a direct problem is of course timeout. But what’s the root reason.
ZooKeeper Client Session Time Out Link to heading
Few pages up, the first beginning of shutdown is:
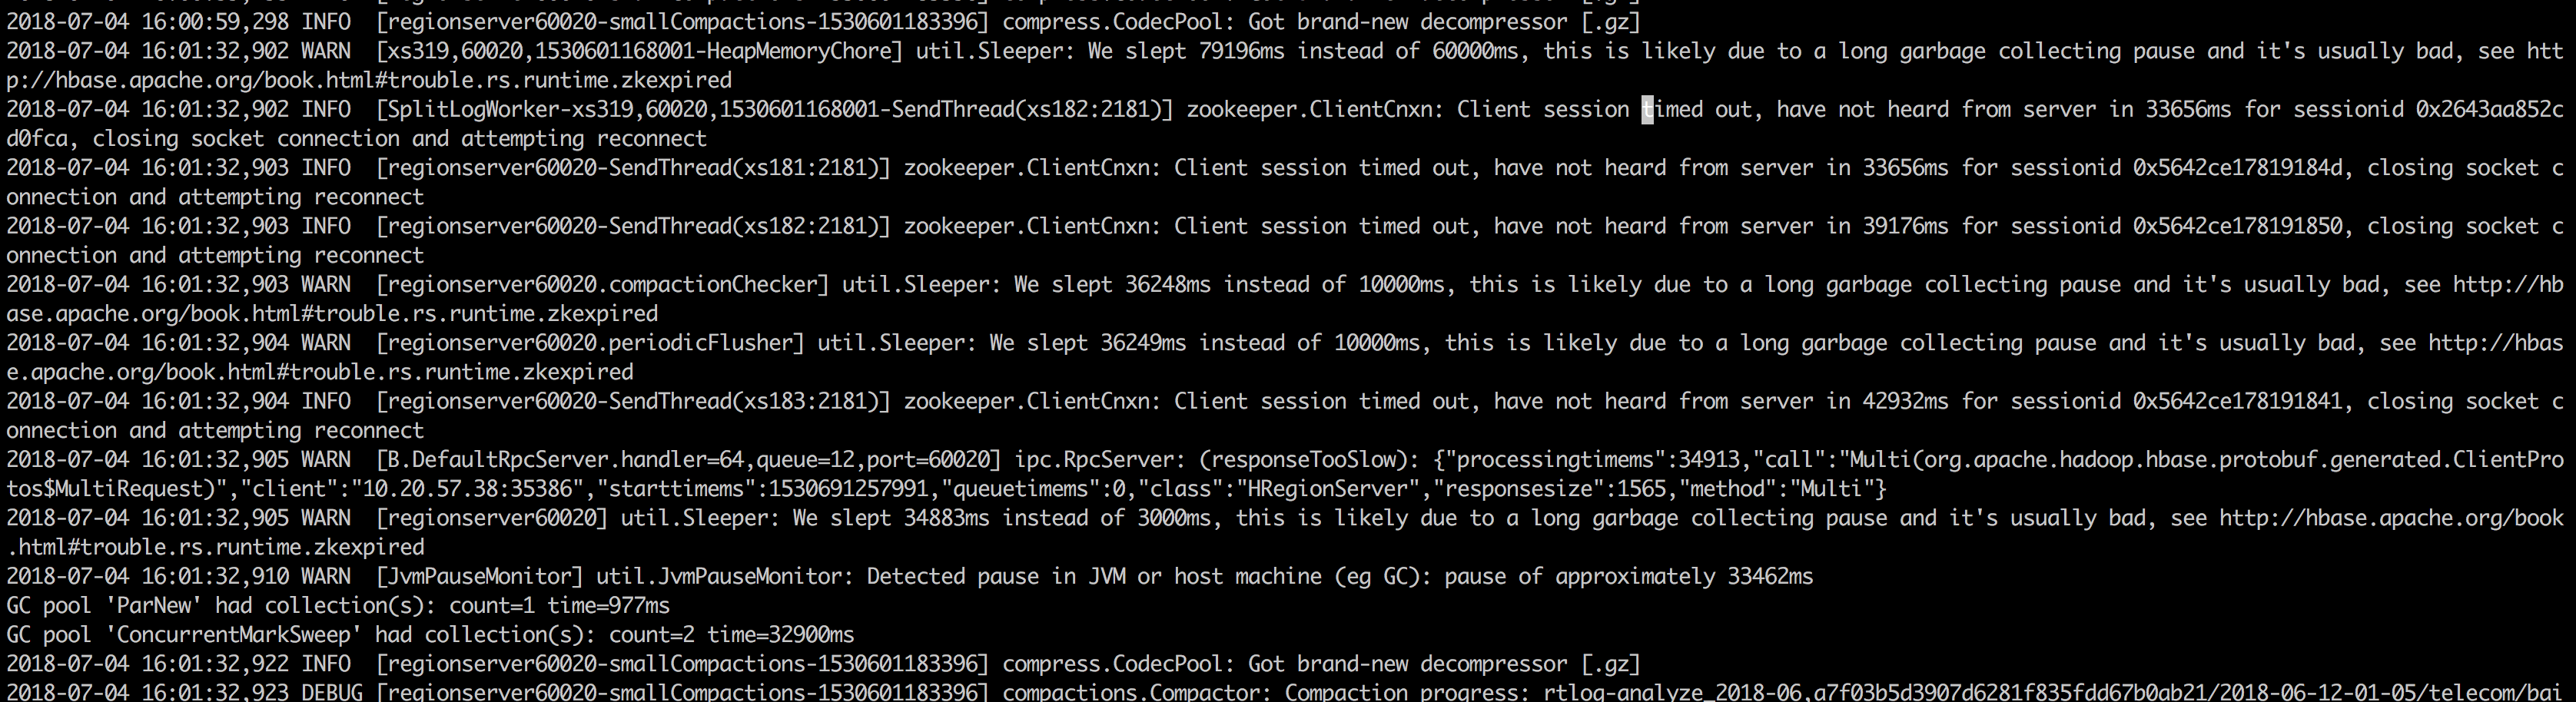
HRegionServer slept for 79s due to a long garabage collection. Finally, the criminal appears.
Explanation Link to heading
Let’s elucidate what happens after Full GC on RegionServer.
- the heartbeat between
RegionServerand Zookeeper stops when Full GC onRegionServer - ZooKeeper deletes node corresponding to the unbearable
RegionServer ServerManageronHMasterfinds there must be something wrong with thisRegionServer, and hands over toServerShutdownHandlerSplitLogManageronHMasterand its slave,SplitLogWorkeronRegionServerstart log splitting. For details, see Apache HBase Log SplittingAssignmentManageronHMasterassigns moribund regions to anotherRegionServer. The logs are replayed by reading the edits and saving them to theMemStore. After all edit files are replayed, the contents of the memstore are written to disk (HFile) and the edit files are deleted.- the reborn regions begin to be available
- when the Full GC stops on the moribund
RegionServer, it try to heartbeat withHMasterbytryRegionServerReport()and received aYouAreDeadException - the mortal
RegionServercloses all the threads and dies